BMM Developer Notes
Overview
Last update: 16.09.2026
This guide aims to help developers contribute new models to bmm. It is a work in progress and will be updated as the package evolves. It explains how to set-up your system for package development, the structure of the package, and the workflow for contributing new models to the package.
The bmm package now supports models across multiple domains, including visual working memory models (mixture models, IMM, SDM), response time / decision models (DDM, EZDM, Censored-Shifted Wald), and categorical response models (M3). The package requires R >= 4.1.0 and uses the native pipe operator |> throughout. Further models are in development on feature branches; they are not part of a release and not covered here until they are.
This guide describes bmm at the v1.3.2 tag. Anything merged after that tag may not be reflected here yet, and the version on CRAN can lag behind the tag while a submission is being processed. If you run into problems, don’t hesitate to open an issue on github.
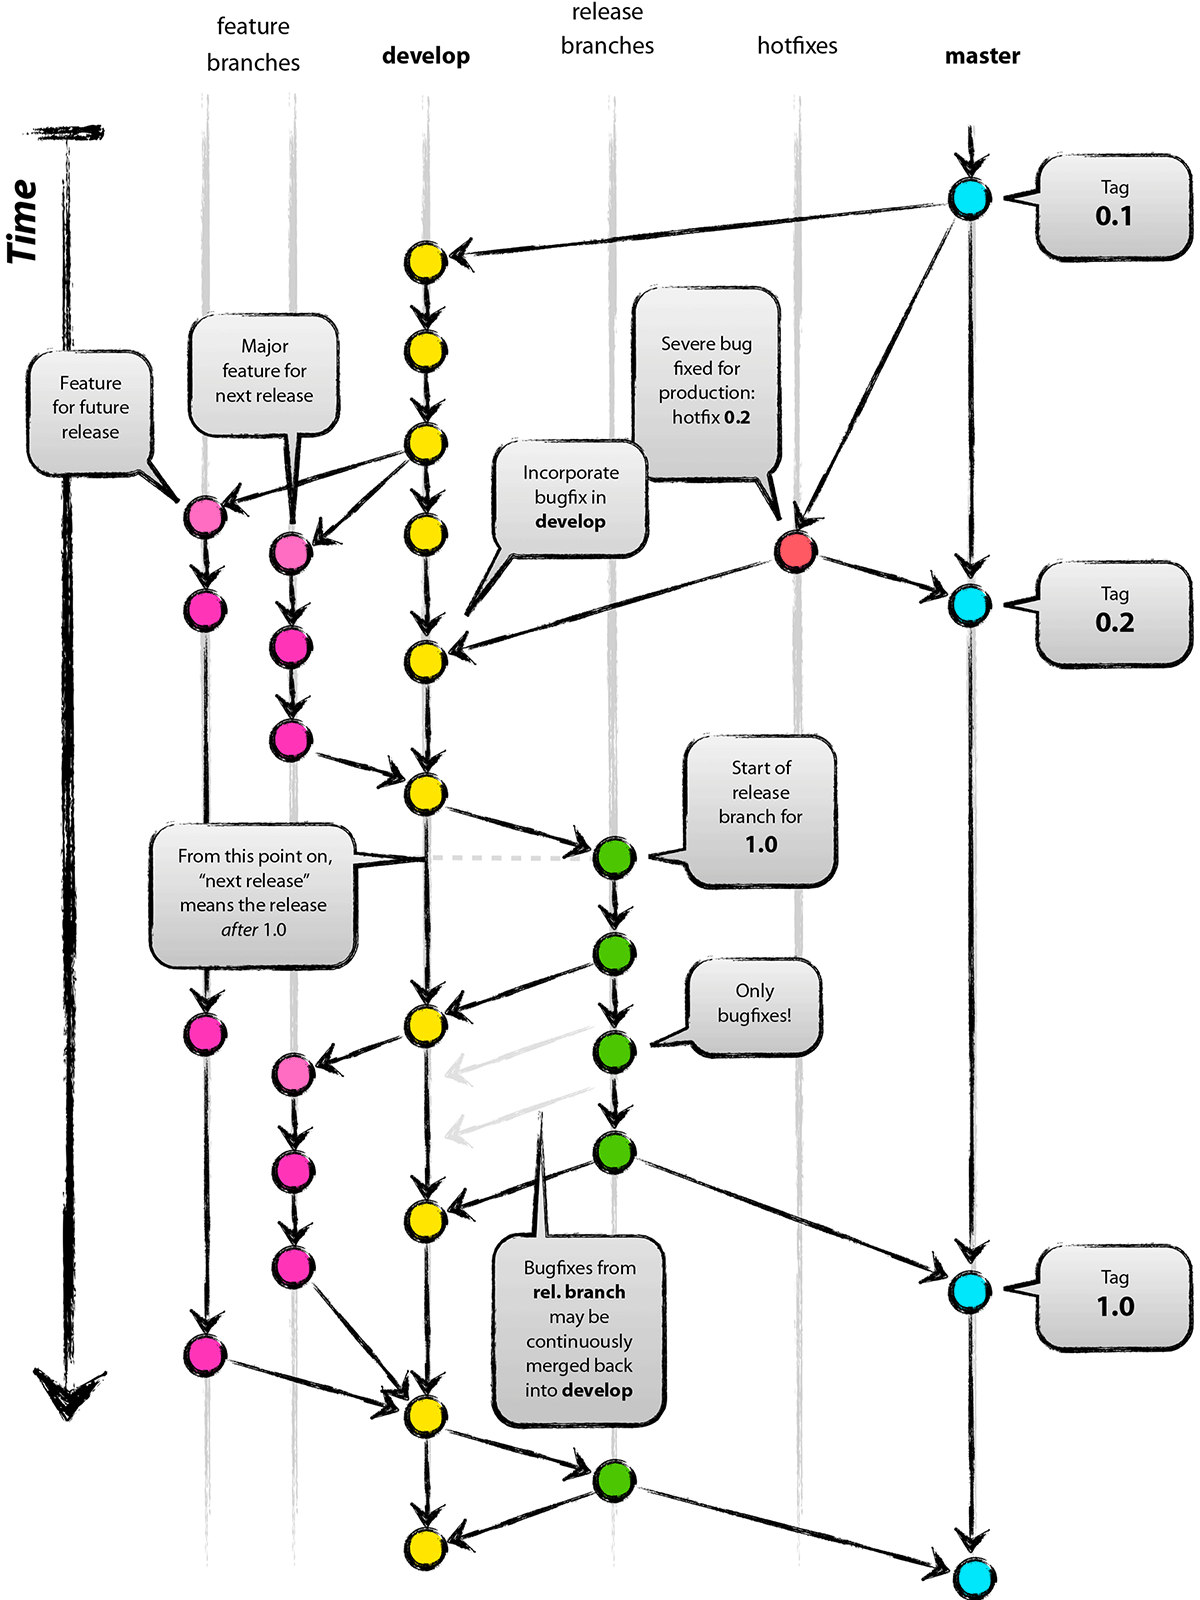
We follow a github flow workflow. The repository contains two main branches:
Master (contains the latest released stable version of the
bmmpackage)Develop (contains the latest stable development branch)
All new feature development should occur on an independent branch from Develop. If you want to contribute a new model to the bmm package, you need to fork the repository, create a new branch for your model off Develop, extensively test the model, and eventually submit a pull request into the Develop branch of the main repository.
How that pull request is reviewed:
One reviewer approval is required to merge. Two are required when the pull request changes shared infrastructure rather than a single model — the pipeline helpers under
R/helpers-*.R, or the exported API — because those changes affect every model rather than only yours.A pull request that adds a new model is approved by a human who has installed your branch and fitted the model. Reading the diff is not sufficient for a new model, because the failure modes that matter (a likelihood that compiles but samples badly, priors that make the model unidentifiable, initial values that hit the boundary) only show up in a fit.
Accordingly, make the model easy to fit for whoever reviews it: include a short, runnable example with a small simulated dataset, and say in the pull request how long it takes to fit and what output to expect.
Once your changes are merged into the Develop branch, they will be included in the next release of the package.